MIL-005: wiki in English, Danish and Bahasa Malaysia #39
@@ -0,0 +1,17 @@
|
|||||||
|
**English** · [Dansk](Gains-da) · [Bahasa Melayu](Gains-ms)
|
||||||
|
|
||||||
|
# What we gained
|
||||||
|
|
||||||
|
| Lecture | What we can do now |
|
||||||
|
| --- | --- |
|
||||||
|
| [Parsing HTML](Parsing-HTML) | Make a soup, read its structure and select elements by tag, id, class or CSS selector |
|
||||||
|
| [Hacker News](Hacker-News) | Fetch a live page, read titles, links and scores, convert text to numbers, find the maximum |
|
||||||
|
| [Scraping ethics](Scraping-Ethics) | Check `robots.txt`, respect copyright and logins, keep requests rare |
|
||||||
|
| [Top 100 movies](Top-100-Movies) | Scrape a ranked list, reverse it and write it to a file |
|
||||||
|
| [Setup](Setup) | Work in a virtual environment with `pyproject.toml` and offline tests |
|
||||||
|
|
||||||
|
## Beyond the lectures
|
||||||
|
|
||||||
|
- **Parsing is separate from fetching.** The parsing functions take text, so the tests use saved pages and never need the network.
|
||||||
|
- **Layers keep rules apart.** The ranking rule has no knowledge of BeautifulSoup or Requests.
|
||||||
|
- **Screenshots are made by a script** (`tools/make_screenshots.py`), so they can be regenerated after a change.
|
||||||
@@ -0,0 +1,57 @@
|
|||||||
|
**English** · [Dansk](Hacker-News-da) · [Bahasa Melayu](Hacker-News-ms)
|
||||||
|
|
||||||
|
# Scraping Hacker News
|
||||||
|
|
||||||
|
Lecture: *Scraping a live website*. The code is `hacker_news.py` (parsing) and `http_client.py` (one `requests.get` with a timeout and a `User-Agent`). The commands read the course's static copy of the page; `--source live` reads the real site and `--source fixture` reads the saved copy without network.
|
||||||
|
|
||||||
|
## Step 1: look at the page
|
||||||
|
|
||||||
|
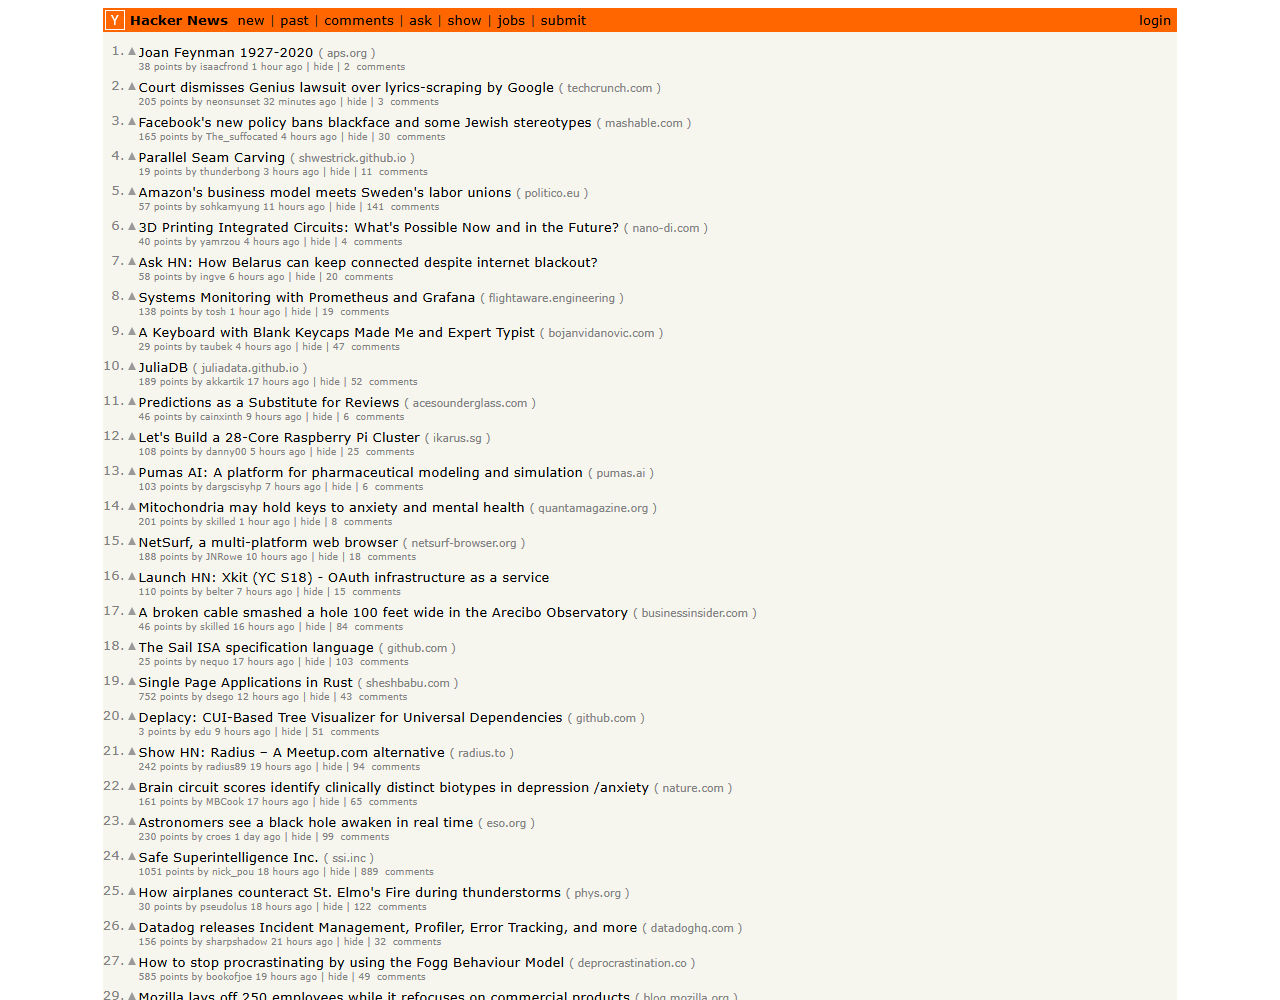
The page lists stories with a title, a link and a score.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** live data is richer than a local file, but it can change, so we also keep a saved copy for tests.
|
||||||
|
|
||||||
|
## Step 2: inspect the markup
|
||||||
|
|
||||||
|
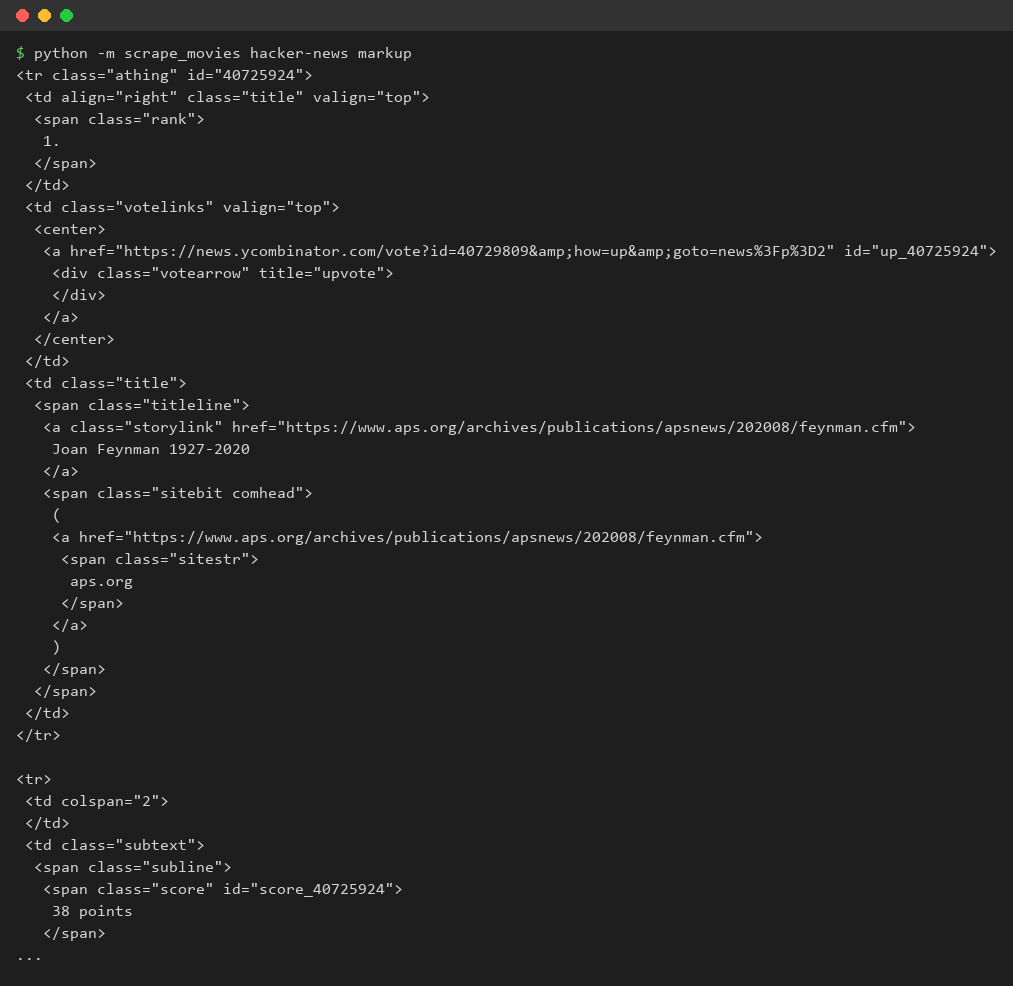
The browser's developer tools show the tags: a row `tr.athing`, the title link `.titleline > a` and a `span.score` in the next row.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** we find the right tag by inspecting the page before we write any code.
|
||||||
|
|
||||||
|
## Step 3: titles
|
||||||
|
|
||||||
|
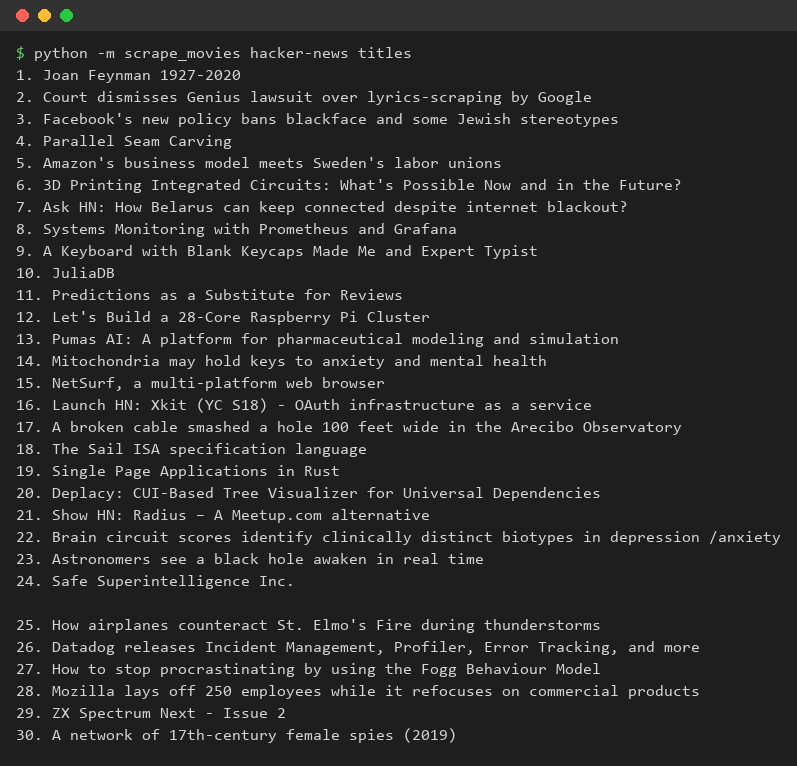
`find_all` on the title links and `get_text()`.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** a list comprehension turns many tags into a plain list of strings.
|
||||||
|
|
||||||
|
## Step 4: links
|
||||||
|
|
||||||
|
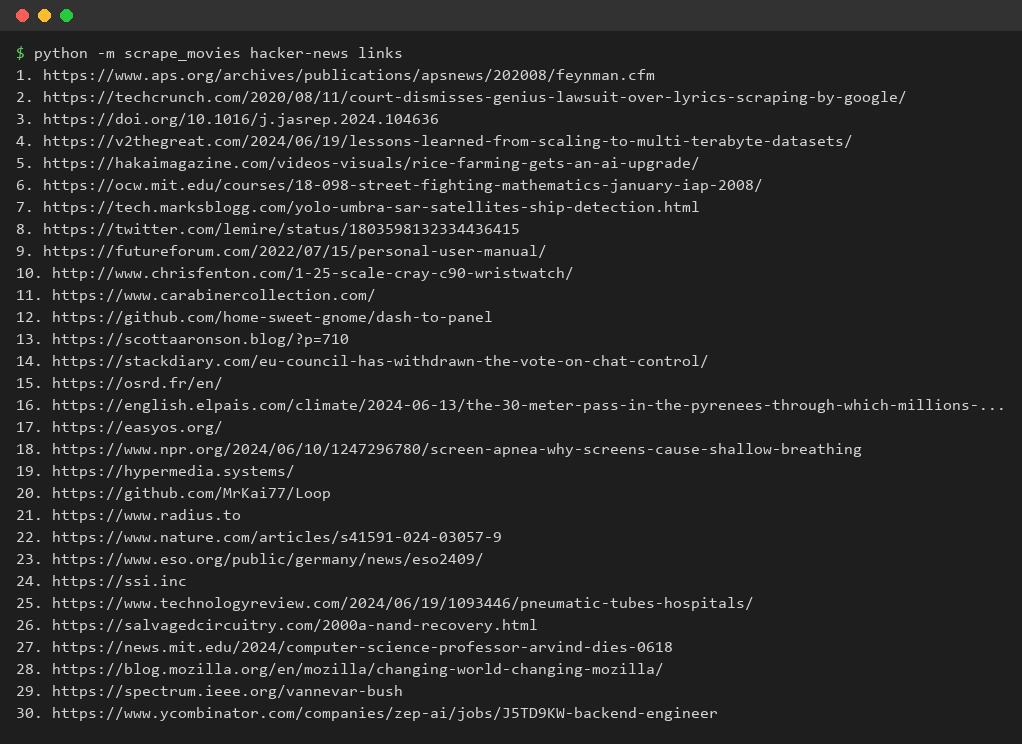
`get("href")` of the same anchors.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** the same element gives both text and attribute values.
|
||||||
|
|
||||||
|
## Step 5: upvotes
|
||||||
|
|
||||||
|
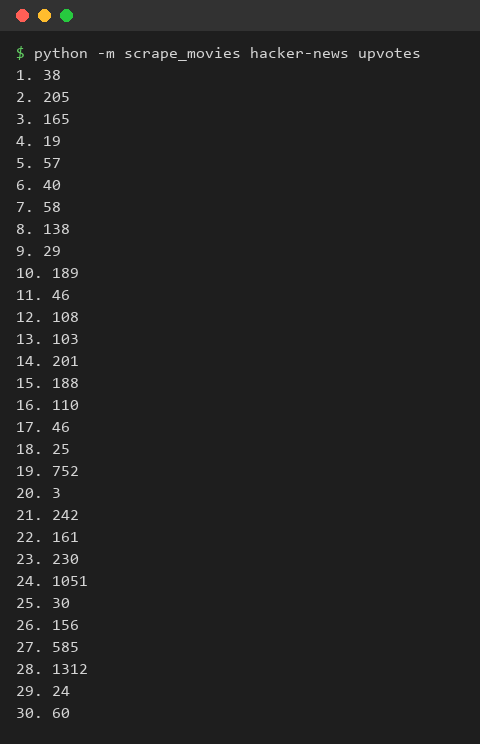
The text `38 points` is split and converted with `int()`.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** scraped text must be converted to numbers before it can be compared.
|
||||||
|
|
||||||
|
## Step 6: the top story
|
||||||
|
|
||||||
|
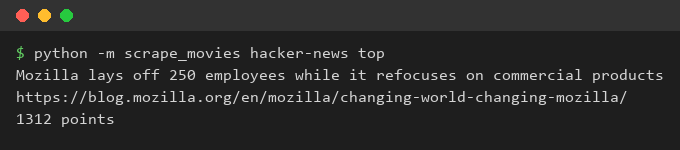
`max` over the upvotes finds the most popular article.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** once the data is clean, ordinary Python answers questions about it.
|
||||||
|
|
||||||
|
## What we gained
|
||||||
|
|
||||||
|
We can fetch a page with Requests, find the rows, read titles, links and scores, convert them to usable types and answer a question about the data.
|
||||||
@@ -0,0 +1,23 @@
|
|||||||
|
**English** · [Dansk](Home-da) · [Bahasa Melayu](Home-ms)
|
||||||
|
|
||||||
|
# scrape-movies wiki
|
||||||
|
|
||||||
|
Day 45 of Udemy's "100 Days of Code: The Complete Python Pro Bootcamp" is about web scraping with Requests and BeautifulSoup. This repository reproduces every lecture step as tested Python code. This wiki shows each step with a screenshot and explains what we gained from it.
|
||||||
|
|
||||||
|
## Pages
|
||||||
|
|
||||||
|
| Page | Lecture | What you get |
|
||||||
|
| --- | --- | --- |
|
||||||
|
| [Setup](Setup) | - | Create the `.venv`, install, run the tests |
|
||||||
|
| [Parsing HTML](Parsing-HTML) | Parsing HTML and making soup; finding and selecting elements | Five steps with screenshots |
|
||||||
|
| [Hacker News](Hacker-News) | Scraping a live website | Six steps with screenshots |
|
||||||
|
| [Scraping ethics](Scraping-Ethics) | Is web scraping legal and ethical? | The rules we follow, with a screenshot of `robots.txt` |
|
||||||
|
| [Top 100 movies](Top-100-Movies) | The 100 movies project | Six steps and `movies.txt` |
|
||||||
|
| [What we gained](Gains) | All lectures | A short summary of the skills |
|
||||||
|
|
||||||
|
## For whom
|
||||||
|
|
||||||
|
- **Coursists:** readable, runnable code that keeps the assignment's ideas; compare it with your own solution.
|
||||||
|
- **Visitors:** a small example with tests and only two runtime dependencies, `requests` and `beautifulsoup4`.
|
||||||
|
|
||||||
|
The code and the documents are in the [repository](https://git.tirsystem.com/Tirsvad-Udemy-100-days-of-code/045-scrape-movies).
|
||||||
@@ -0,0 +1,49 @@
|
|||||||
|
**English** · [Dansk](Parsing-HTML-da) · [Bahasa Melayu](Parsing-HTML-ms)
|
||||||
|
|
||||||
|
# Parsing HTML
|
||||||
|
|
||||||
|
Lectures: *Parsing HTML and Making Soup* and *Finding and Selecting Elements*. The sample page is `tests/fixtures/website.html`; the code is `soup_basics.py`.
|
||||||
|
|
||||||
|
## Step 1: create a soup and read the title
|
||||||
|
|
||||||
|
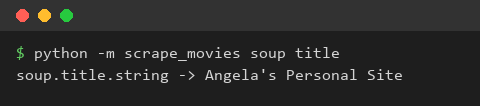
`BeautifulSoup(html, "html.parser")` turns the HTML text into a soup object. `soup.title.string` is the text of the title tag.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** HTML text becomes an object we can navigate, and a tag is reached with plain attribute access.
|
||||||
|
|
||||||
|
## Step 2: prettify
|
||||||
|
|
||||||
|
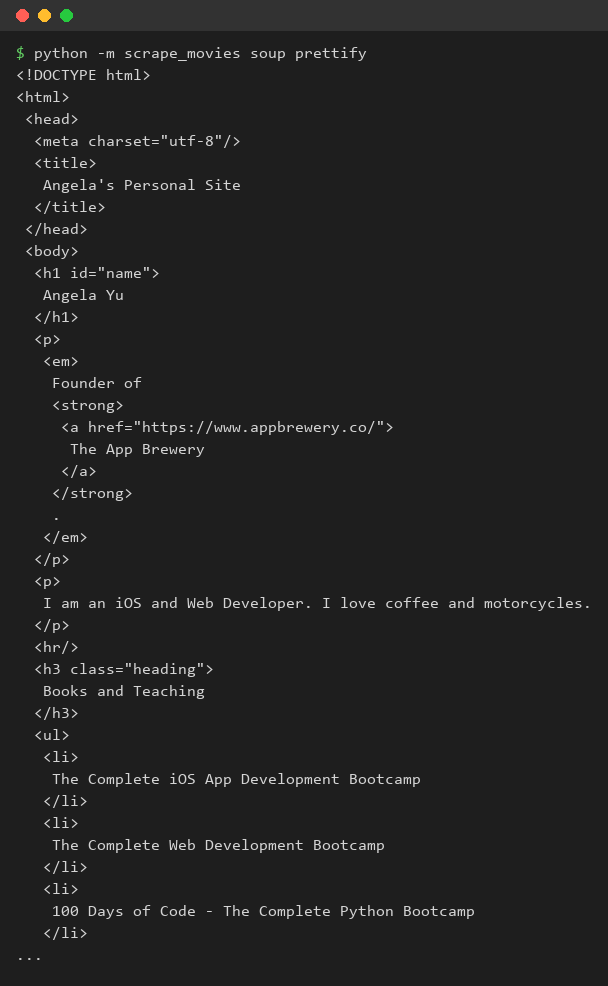
`soup.prettify()` writes the document with one tag per line, which makes the nesting visible.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** reading the structure first tells us what to ask for.
|
||||||
|
|
||||||
|
## Step 3: find all tags
|
||||||
|
|
||||||
|
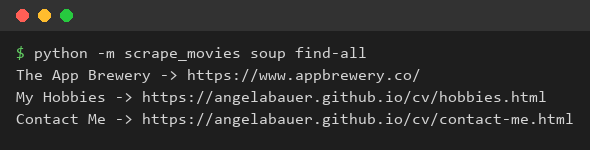
`find_all("a")` returns every anchor. In a loop, `get_text()` gives the text and `get("href")` the address.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** one call finds many elements, and a loop turns them into data.
|
||||||
|
|
||||||
|
## Step 4: find by id and by class
|
||||||
|
|
||||||
|
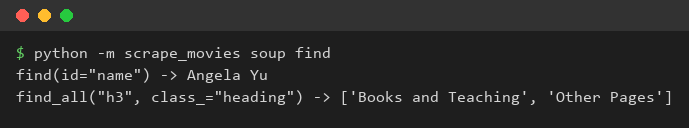
`find(id="name")` finds one tag by its id. `find_all("h3", class_="heading")` filters by tag and class; the keyword is `class_` because `class` is a Python keyword.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** attributes narrow a search, and we avoid clashes with reserved words.
|
||||||
|
|
||||||
|
## Step 5: CSS selectors
|
||||||
|
|
||||||
|
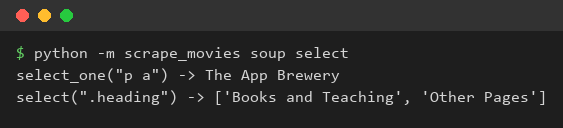
`select_one("p a")` and `select(".heading")` use the same selectors as CSS, so nested elements are reached in one expression.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** CSS selectors are the shortest way to describe where an element sits in the document.
|
||||||
|
|
||||||
|
## What we gained
|
||||||
|
|
||||||
|
We can read an HTML file into BeautifulSoup, look at its structure and pick out single or many elements by tag, id, class or CSS selector.
|
||||||
@@ -0,0 +1,24 @@
|
|||||||
|
**English** · [Dansk](Scraping-Ethics-da) · [Bahasa Melayu](Scraping-Ethics-ms)
|
||||||
|
|
||||||
|
# Is web scraping legal and ethical?
|
||||||
|
|
||||||
|
Lecture: *The legal and ethical side of web scraping*. This is a summary in our own words, not legal advice.
|
||||||
|
|
||||||
|
## Step 1: read robots.txt first
|
||||||
|
|
||||||
|
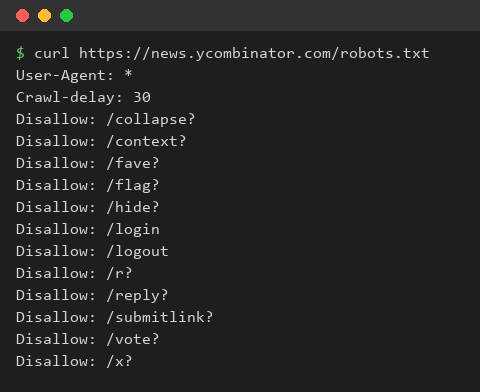
A site's `robots.txt` says what it allows. Hacker News disallows some paths and asks for a crawl delay of 30 seconds.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** we check the rules before we scrape, and we keep our requests rare: this project fetches one page per run.
|
||||||
|
|
||||||
|
## The rules we follow
|
||||||
|
|
||||||
|
- Public data that is not copyrighted is generally fine to read. The cases Genius v. Google and hiQ v. LinkedIn show that the line is not simple.
|
||||||
|
- Copyrighted content, such as videos or blog posts, must not be copied. Data behind a login is covered by the site's user agreement.
|
||||||
|
- Commercial use of scraped data can lead to costly disputes even when the scraping itself was allowed.
|
||||||
|
- Prefer an official API, respect `robots.txt`, send a `User-Agent` and do not send more than one request a minute.
|
||||||
|
|
||||||
|
## What we gained
|
||||||
|
|
||||||
|
Scraping is a technical skill with legal and ethical limits. Knowing the limits is part of doing it well.
|
||||||
@@ -0,0 +1,38 @@
|
|||||||
|
**English** · [Dansk](Setup-da) · [Bahasa Melayu](Setup-ms)
|
||||||
|
|
||||||
|
# Setup
|
||||||
|
|
||||||
|
You need Python 3.13 or newer. Everything below is run from the repository root.
|
||||||
|
|
||||||
|
## Create the virtual environment
|
||||||
|
|
||||||
|
```powershell
|
||||||
|
python -m venv .venv
|
||||||
|
.venv\Scripts\Activate.ps1
|
||||||
|
python -m pip install --upgrade pip
|
||||||
|
python -m pip install -e ".[dev]"
|
||||||
|
```
|
||||||
|
|
||||||
|
On Linux and macOS use `python3 -m venv .venv` and `source .venv/bin/activate`.
|
||||||
|
|
||||||
|
## Run a lecture step
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python -m scrape_movies soup title
|
||||||
|
python -m scrape_movies hacker-news top
|
||||||
|
python -m scrape_movies movies write
|
||||||
|
```
|
||||||
|
|
||||||
|
## Run the tests
|
||||||
|
|
||||||
|
```bash
|
||||||
|
python -m pytest
|
||||||
|
```
|
||||||
|
|
||||||
|
The tests use saved pages from `tests/fixtures/` and never touch the network.
|
||||||
|
|
||||||
|
## What we gained
|
||||||
|
|
||||||
|
- A virtual environment keeps the project's packages apart from the system Python.
|
||||||
|
- `pyproject.toml` is the one place for the Python version, the dependencies and the tool settings.
|
||||||
|
- Tests that run offline give the same result on every machine.
|
||||||
@@ -0,0 +1,59 @@
|
|||||||
|
**English** · [Dansk](Top-100-Movies-da) · [Bahasa Melayu](Top-100-Movies-ms)
|
||||||
|
|
||||||
|
# Top 100 movies
|
||||||
|
|
||||||
|
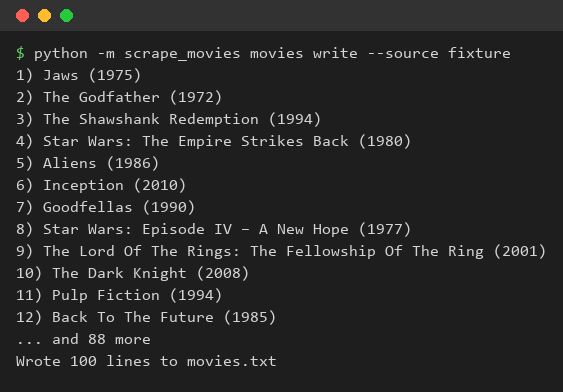
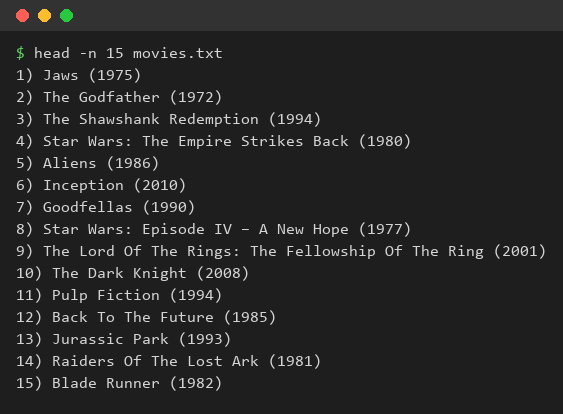
Lecture: *The 100 movies project*. The goal is `movies.txt` with the titles numbered from `1)` upwards. The code is `empire_movies.py` (parsing), `movie.py` (reverse and number) and `movie_file.py` (writing).
|
||||||
|
|
||||||
|
## Step 1: choose the page
|
||||||
|
|
||||||
|
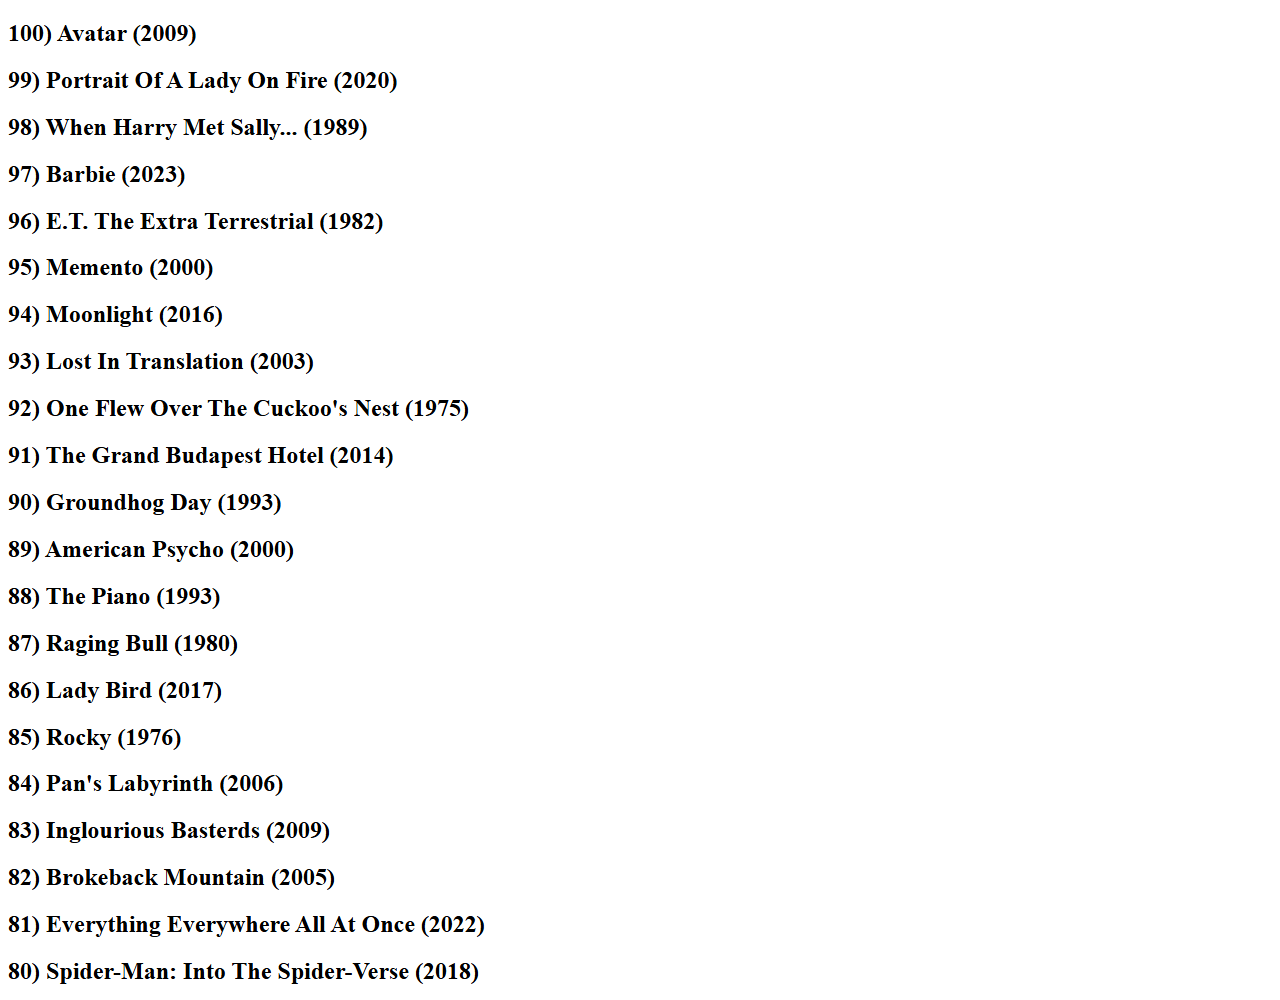
The assignment pins an Internet Archive snapshot of Empire's list, because live sites change. The screenshot shows the saved headings of the page.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** a pinned snapshot makes a scraper repeatable.
|
||||||
|
|
||||||
|
## Step 2: inspect the markup
|
||||||
|
|
||||||
|
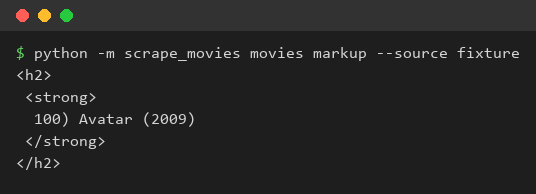
The 2020 page has `<h3 class="title">`; the current page has `<h2><strong>` headings that start with a rank.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** when a site changes its markup, the parser must change with it, so we keep both layouts covered.
|
||||||
|
|
||||||
|
## Step 3: titles in page order
|
||||||
|
|
||||||
|
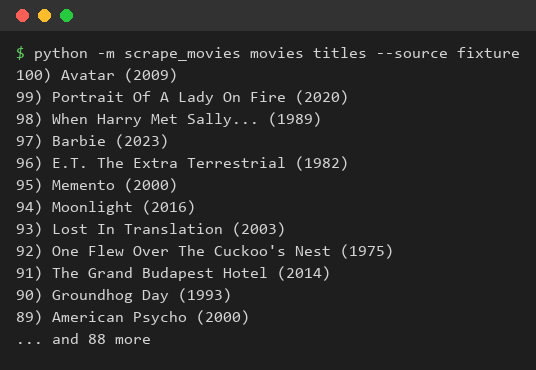
`select("h3.title")` and a list comprehension over `get_text()`. The page counts down from 100.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** a list comprehension is the compact way to collect text from many tags.
|
||||||
|
|
||||||
|
## Step 4: reverse the list
|
||||||
|
|
||||||
|
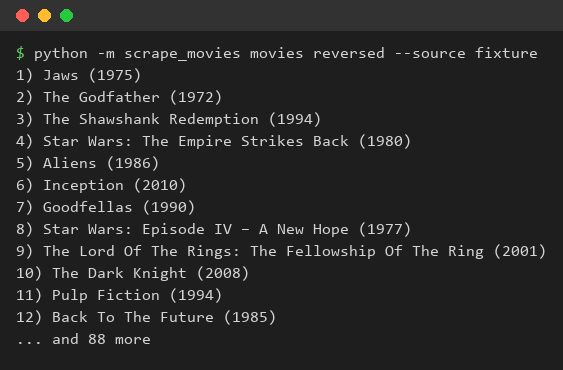
`titles[::-1]` makes the list count up from 1.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** slicing with a negative step reverses a list in one expression.
|
||||||
|
|
||||||
|
## Step 5: write movies.txt
|
||||||
|
|
||||||
|
A `with open(...)` block writes one title per line.
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** the context manager closes the file for us, and the same run always gives the same file.
|
||||||
|
|
||||||
|
## Step 6: the result
|
||||||
|
|
||||||
|
|
||||||
|
|
||||||
|
**What we gained:** a personal watch list from a website, ready to pick a film from at random.
|
||||||
|
|
||||||
|
## Note on the data
|
||||||
|
|
||||||
|
`movies.txt` was produced from the current Empire list on 2026-10-28, so its ranking differs from the 2020 list in the lecture. The Internet Archive answered `429 Too Many Requests` while we built this, so the snapshot layout is covered by a hand-written sample in the tests.
|
||||||
|
|
||||||
|
## What we gained
|
||||||
|
|
||||||
|
We can scrape a ranked list, put it in the order we want and save it to a file.
|
||||||
Reference in New Issue
Block a user